nanodrr


A performance-oriented reimplementation of DiffDRR with the following improvements:
- Optimized, pure PyTorch implementation (~5× faster than
DiffDRRat baseline) - Fused Triton rendering kernel, used by default on CUDA (up to ~80× faster than
DiffDRR) - Modular design (freely swap subjects, extrinsics, and intrinsics during rendering)
- Compatibility with
torch.compileand mixed precision - Extensive type hints with
jaxtyping - Runs on CUDA, Apple silicon (MPS), and CPU
- Standard Python package structure managed with
uv
All projective geometry is implemented internally using the standard Hartley and Zisserman pinhole camera formulation.
All changes to DiffDRR are summarized here.
Installation
PyTorch version
On pytorch<2.9, torch.compile with bfloat16 is slower than eager for the pure PyTorch backend due to a CUDA graph capture issue (see Benchmarks). The fused Triton backend is unaffected.
MPS-accelerated differentiable rendering requires pytorch>=2.13, which is the first release with native MPS kernels for grid_sample backwards and 3D nearest-neighbor sampling.
To strictly install the renderer:
To install the optional plotting or 3D visualization module:
pip install "nanodrr[plot]"   # 2D visualization (matplotlib, opencv)
pip install "nanodrr[scene]"  # 3D visualization (VTK, PyVista)
pip install "nanodrr[all]"    # All extras
Benchmarks
Highlights
- ~5× faster than
DiffDRRwith the pure PyTorch backend (1,093 FPS vs 223 FPS) - ~57× faster with the fused Triton kernel, without compilation (12,600 FPS vs 223 FPS)
- ~80× faster with
torch.compileandbfloat16(17,820 FPS vs 223 FPS) - ~3.5× less memory than
DiffDRR(322 MB vs 1,170 MB peak reserved withbfloat16+ compile)
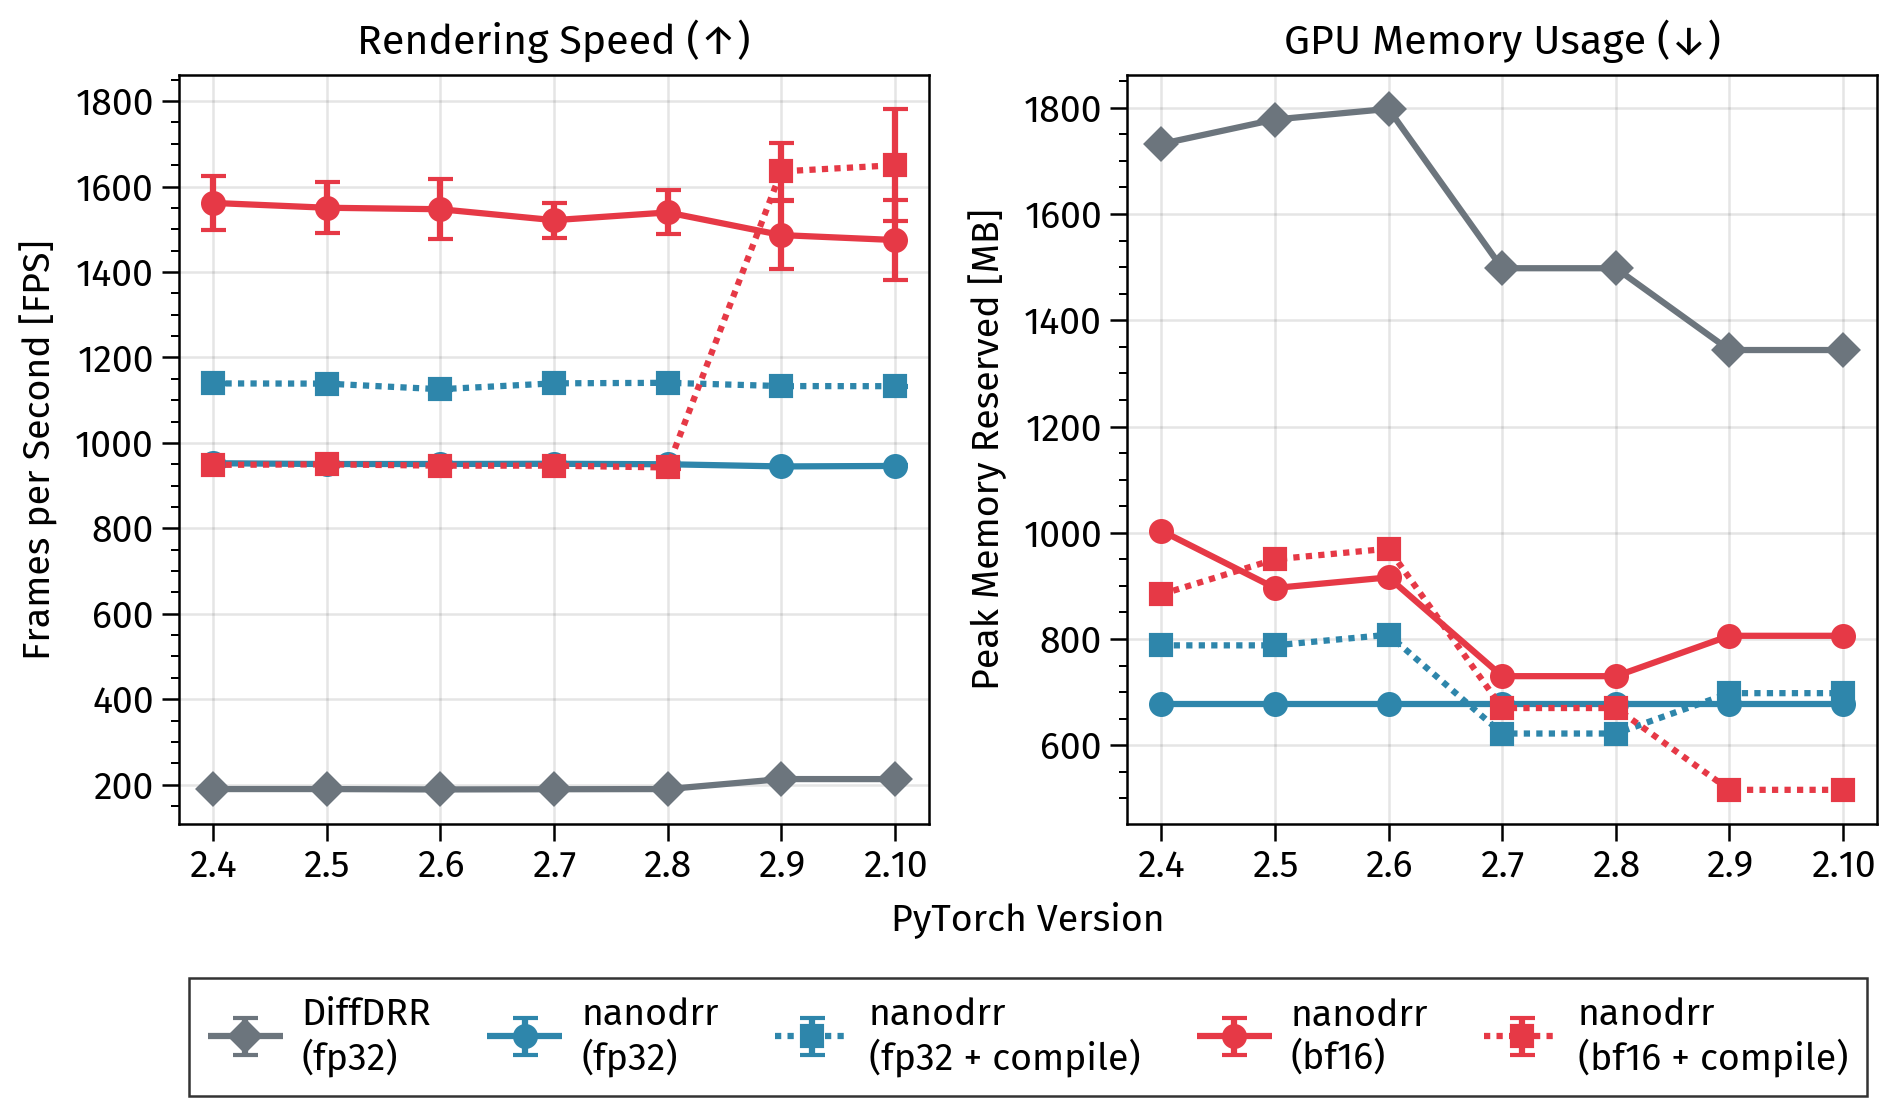
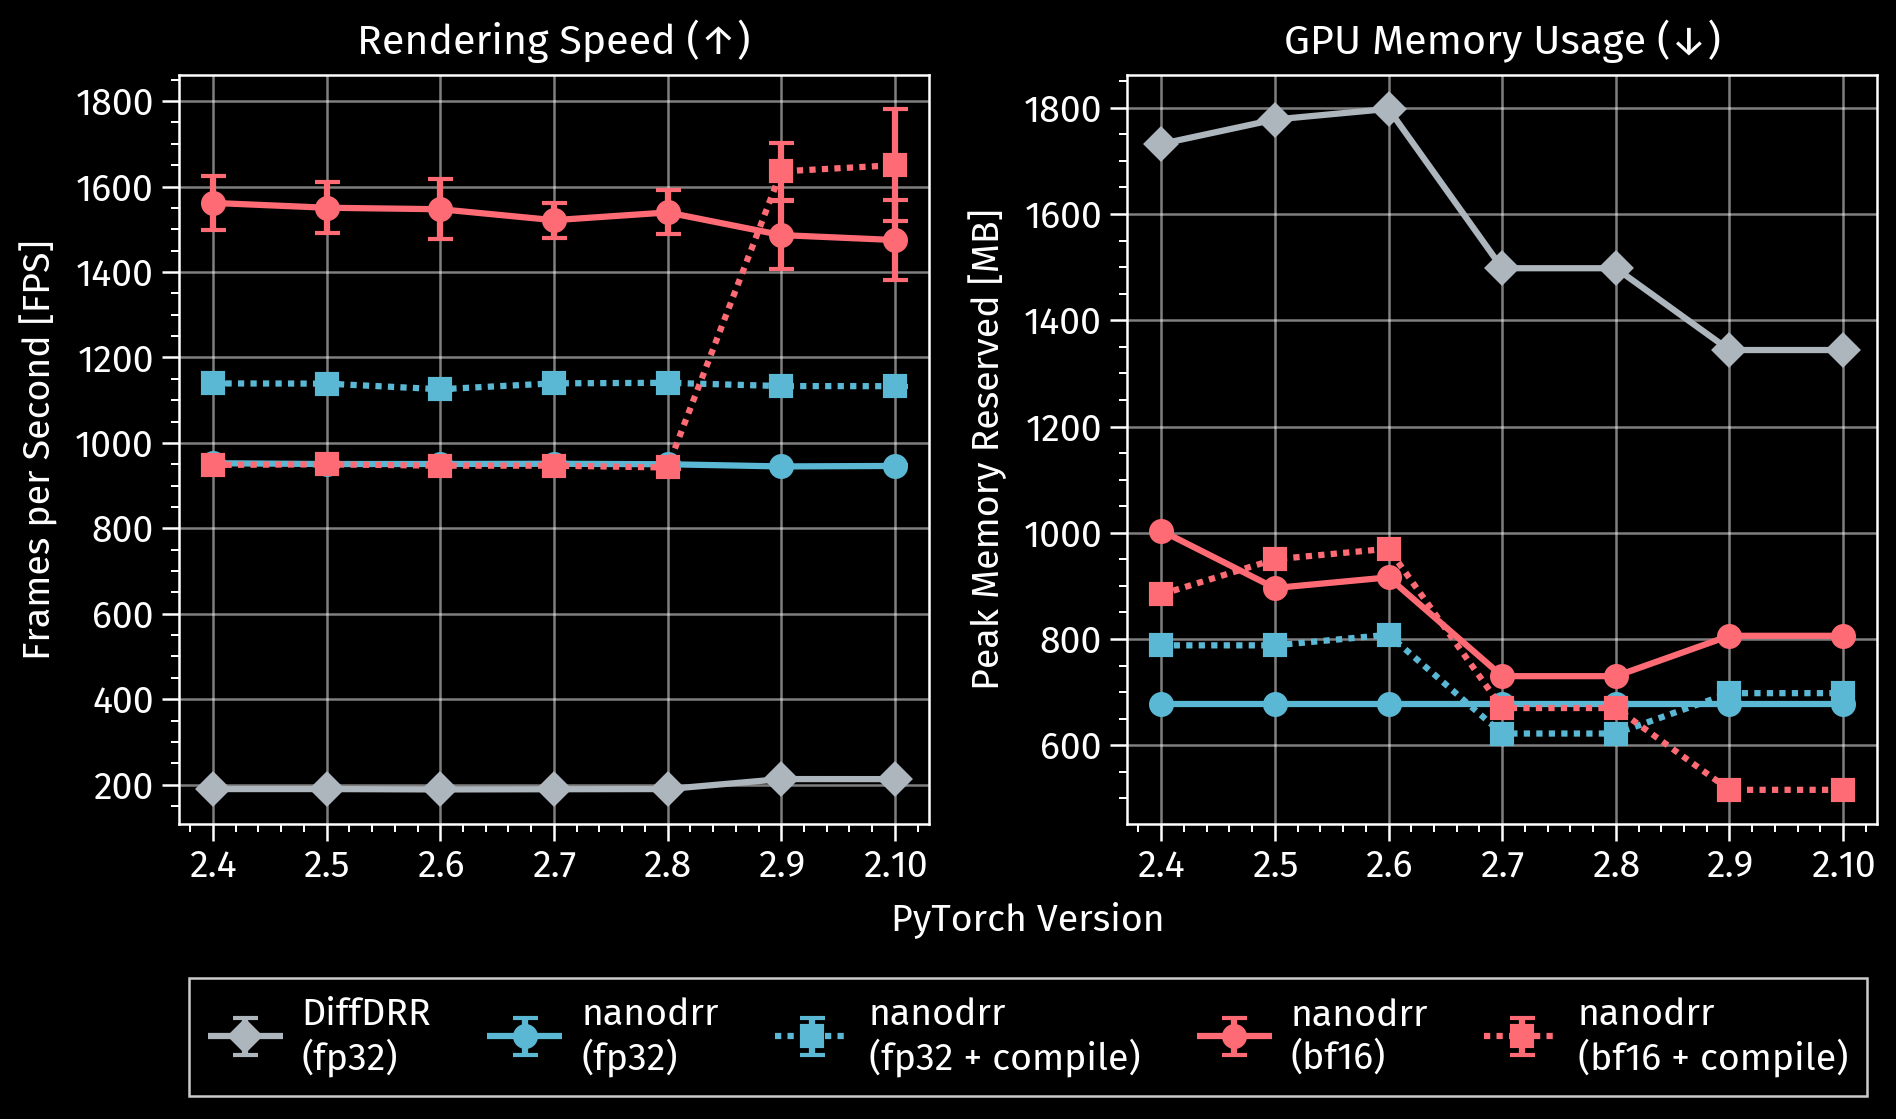
FPS computed from per-frame GPU kernel time (torch.profiler).
Median wall-clock timings are also recorded in tests/benchmark/benchmark.csv. Benchmarked by rendering 200×200 DRRs on an NVIDIA RTX 6000 Ada (48 GB) with Python 3.12. Compile represents torch.compile(mode="reduce-overhead", fullgraph=True). Full experiment at tests/benchmark/.
Roadmap
- Implement a fully optimized renderer
- Port strictly necessary modules from
DiffDRR(e.g., SE(3) utilities, loss functions, and 2D plotting) - Migrate 3D plotting functions to an optional module
- Integrate with
xvrto speed up network training and registration - Integrate with
polyposeto speed up registration - Release as
v1.0.0ofDiffDRR!